How to Extract Text from PDF for Free
Table of Contents
Extracting text from a PDF lets you reuse its content in documents, notes, or other applications. If the text is selectable, you can simply copy and paste it. For scanned PDFs or images, you’ll need OCR to recognize the words first.
This guide shows you how to extract text from a PDF for free, save it as plain text (TXT), or convert it to an editable Word document.
Extract Text from PDF Online by Copying Quickly
For a regular PDF, the quickest way to extract text is to select and copy the words you need. You can do this directly in your browser or with PDFgear Online Editor for free.
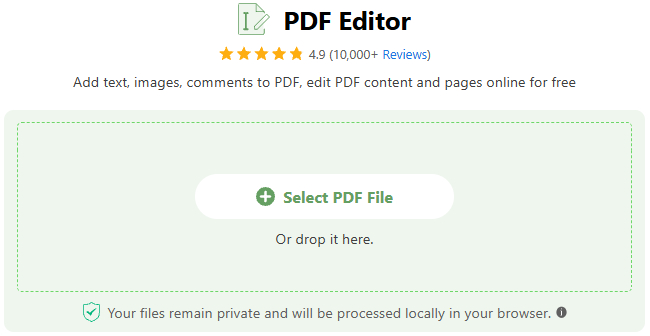
Extract Text from PDF Online without Installation
1. Open PDFgear Online Editor, click Select PDF File, and choose your PDF.
2. Drag across the words you want. Right-click and choose Copy, or press Ctrl+C on Windows or Command+C on Mac. (You can drag to select text across multiple PDF pages and copy it all at once, without copying each page separately.)
3. Paste into a note, document, or text editor. Compare the pasted passage with the PDF, especially paragraph breaks, names, and numbers
Scanned PDFs Need OCR:
This works well for a few paragraphs and regular PDFs. If your PDF contains scanned images, you may not be able to select or copy the text directly. In that case, you’ll need OCR to extract the text.
Extract Text from Selected PDF Area with OCR
As mentioned earlier, you can simply copy and paste text from a regular PDF. But if your PDF is scanned or image-based, the text can’t be selected or copied directly.
That’s where OCR (Optical Character Recognition) comes in. With PDFgear, you can use OCR to recognize and extract text from a selected area for free.
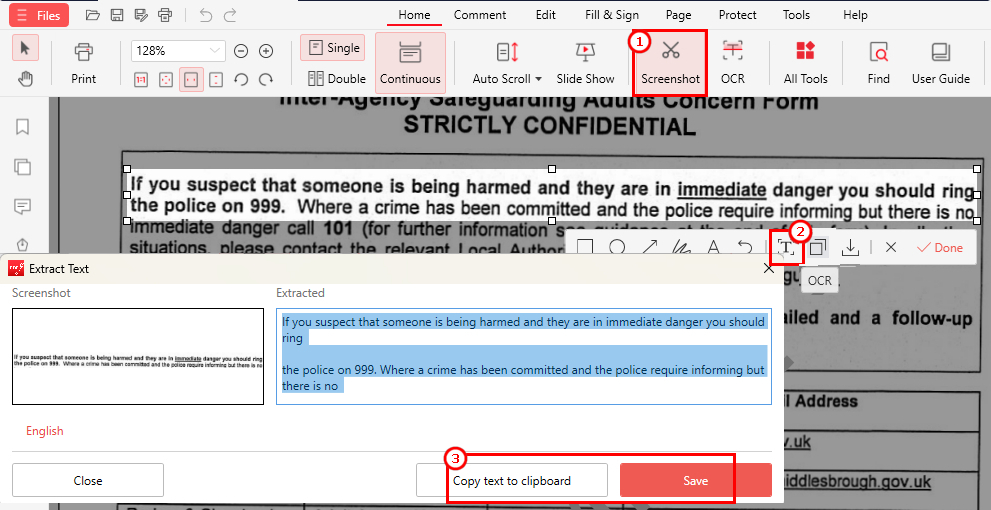
Extract Text from Selected PDF Area with PDFgear Software
1. Download PDFgear and open your PDF.
2. On Windows, go to Home > Screenshot, click OK if prompted. On Mac, choose OCR > Screenshot OCR.
3. Drag to select the text area. On Windows, click OCR on the floating toolbar to recognize the text. On Mac, the text is automatically recognized after you select the area.
4. Check the recognition language and extracted text. If the language is wrong, select the correct one and recognize the area again. Review paragraph breaks and easily confused characters such as 0/O and 1/l.
5. Copy the result or save it as TXT. Windows: use Copy text to clipboard or Save. Mac: use Copy Text or Export.
Working with Longer PDFs:
This method works best for extracting specific sections. If you need text from many pages, exporting the document as TXT can save you from repeating the process.
Extract All Text from PDF as TXT
When you need text from an entire PDF, you can export it as a TXT file without manually copying each page. With PDFgear for Mac, you can use OCR to extract text from all pages or selected pages and save the results as a single TXT file.
1. Open the PDF in PDFgear for Mac and choose OCR > Current File OCR.
2. Select the pages to extract (or all pages), choose the language, and click Start OCR.
3. Once OCR finishes, review the text and choose Export to one file to save the selected pages as a single TXT file, or Export to separated files to save each page as a separate TXT file.
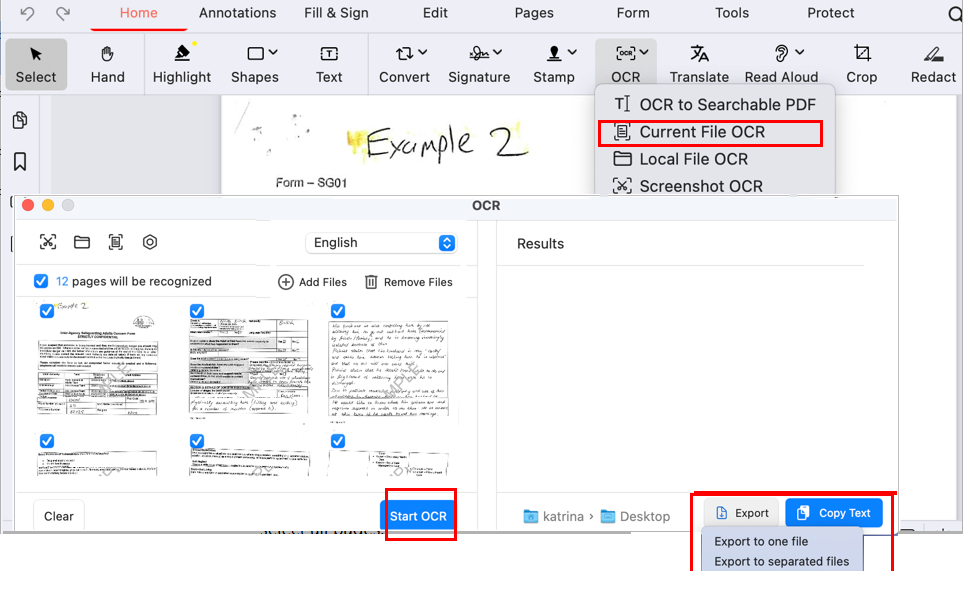
Extract Text from All PDF Pages to TXT
What TXT Files Preserve:
TXT files contain only plain text, so the original fonts, images, and page layout won’t be preserved. If you want to keep editing the extracted content with more of its formatting intact, converting the PDF to Word is a better option.
Extract PDF Text to Word While Preserving Formatting
If you want to reuse PDF text while keeping some of the original formatting, converting the PDF to Word is a practical choice. PDFgear’s online converter creates an editable DOCX file, with an OCR option for scanned documents.
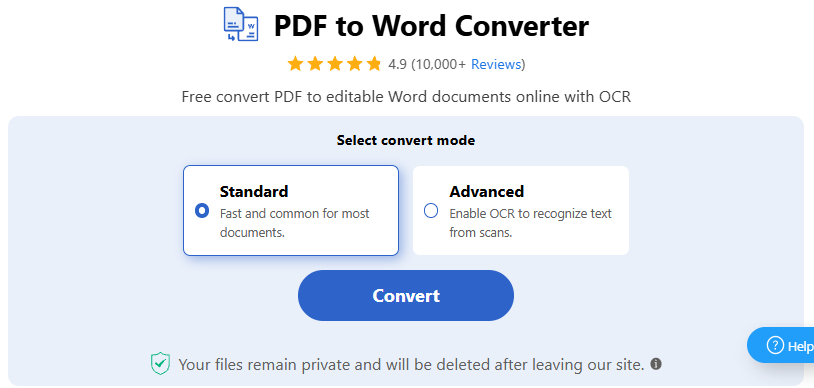
Extract Text from PDF Online by Converting It to Word
1. Open PDFgear PDF to Word Online. Click Select PDF File and choose your PDF.
2. Select Standard for an ordinary text PDF, or Advanced to enable OCR for scanned or image-based PDFs.
3. Click Convert. When conversion finishes, click Download File to save the DOCX.
4. Open the DOCX in a compatible app. You can now copy the text, edit it, or save it in another format.
Check the Extracted Text for Accuracy:
Compare the extracted text with the original PDF, especially for missing passages, page order, and important numbers.
Extract PDF Text with Adobe Acrobat Reader
If you already use Adobe Acrobat Reader, you can extract text from a PDF for free, as long as the text can be selected and copied.
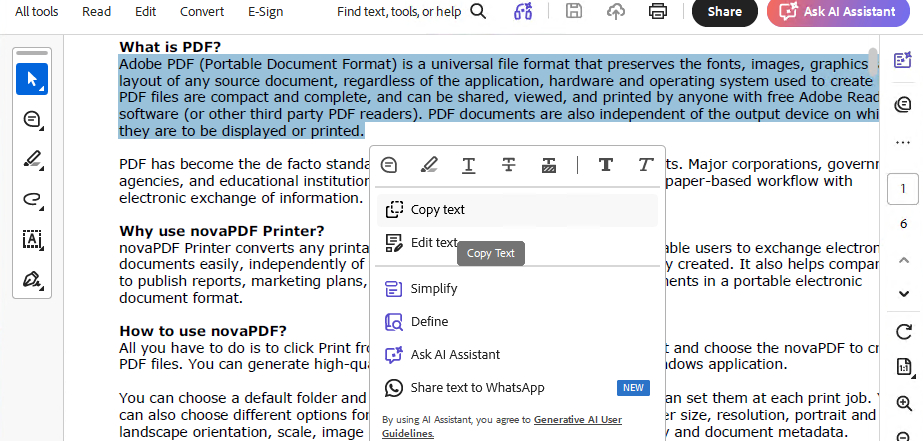
How to Extract Text from PDF with Adobe Acrobat Reader
1. Open your PDF in Adobe Acrobat Reader.
2. Drag your cursor over the text you want to extract.
3. Right-click and choose Copy, or press Ctrl+C on Windows or Command+C on Mac to further use the content.
Scanned PDFs Require Paid Acrobat:
Adobe Acrobat Reader can copy existing text for free, but recognizing text in image-only PDFs requires OCR. This feature is available in paid Acrobat plans, such as Acrobat Pro. Alternatively, you can use PDFgear to extract text from a scanned PDF for free.
Extract PDF Text with Microsoft Word
You can also open a PDF directly in Microsoft Word and work with its text like a regular document. This method works best for PDFs that mainly contain text.
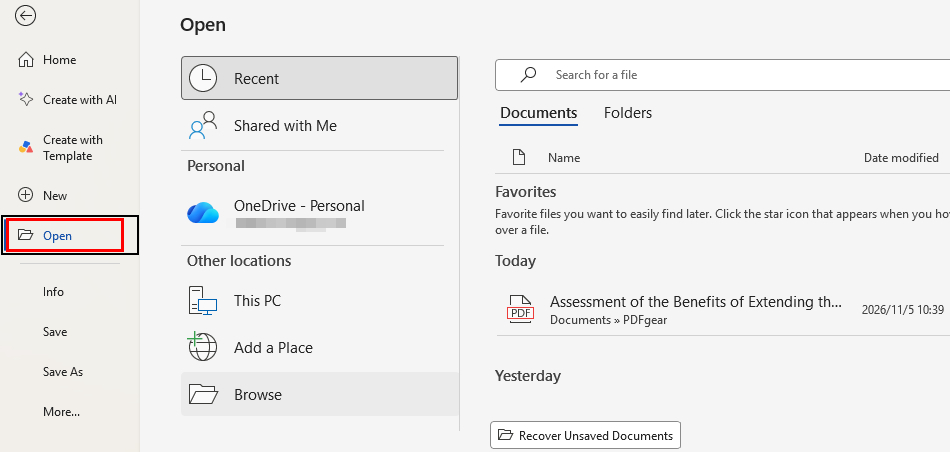
How to Extract Text from PDF Using Word
1. Open Microsoft Word and go to File > Open to select your PDF.
2. Click OK when Word asks to convert the PDF into an editable document.
3. Once Word opens the PDF, you can work with its text just like in a regular Word document.
Formatting May Change:
Word may not preserve the original layout, especially for tables, columns, and images. Scanned PDFs may also remain as images, making the text impossible to edit or copy directly.
For scanned documents, you can use PDFgear’s online PDF to Word converter with Advanced mode to recognize the text and convert it into an editable Word document for free.
Compare PDF Text Extraction Methods
Different PDF text extraction methods work best for different tasks. The table below compares what each tool can do, from copying a few words to extracting an entire document.
| Features | PDFgear Online Editor | PDFgear PDF to Word Online | PDFgear Software | Adobe Reader | Microsoft Word |
| Best for | Quick copy | Full PDF | Area OCR / TXT | Quick copy | PDF editing |
| Scanned PDF | No | Yes (OCR) | Yes (OCR) | No | No |
| Scope | Manual | Whole PDF | Area / Pages | Manual | Whole PDF |
| Output | Clipboard | DOCX | Copy / TXT | Clipboard | DOCX |
| Access / Cost | Online / Free | Online / Free | Desktop / Free | Desktop / Free | Desktop / Require License |
This table compares the extraction methods described above, not every feature available in each product.
FAQs
How do I save extracted PDF text as a TXT file?
For PDFs with selectable text, simply copy the text, paste it into a text editor like Notepad or TextEdit, and save it as a TXT file.
For scanned or image-based PDFs, use PDFgear’s OCR feature to recognize the text first, then export it directly as TXT.
Why can’t I extract text from my PDF?
There are a few possible reasons:
- Scanned or image-based PDF: Use OCR to recognize the text before copying it from scanned PDFs.
- Copying restrictions: Check the PDF’s permissions. If you have authorization, you can copy text from a secured PDF.
- Garbled or missing text: Try another extraction method or check the text encoding or try OCR to fix gibberish text copied from a PDF.
Can I extract text from a PDF without uploading it?
Yes. You can open a regular PDF in PDFgear Software and copy its text directly without uploading the file.
Even better, PDFgear Online Editor also processes files locally in your browser, so you can extract text without uploading your PDF to a server or installing software.
Will extracted PDF text keep its original formatting?
It depends on the output format. TXT keeps only plain text, while DOCX can preserve some formatting, though tables, fonts, and complex layouts may change. If you want to keep the original PDF appearance while making its text searchable, you can make a PDF searchable instead.
Can ChatGPT Extract Text from a PDF?
Yes. ChatGPT can extract text from PDFs, but it may miss or alter content, especially in scanned or complex documents. For more accurate results, use a dedicated PDF text extractor like PDFgear and verify the output.
Can I extract text from a PDF using Python?
Yes. You can use Python libraries like pypdf and page.extract_text() to extract text from PDF pages. Scanned PDFs require OCR. See the pypdf documentation for details.
Conclusion
Extracting text from a PDF is easy with the right method. You can copy text directly, use OCR for scanned PDFs, or save the content as TXT or Word for further use. PDFgear offers free options for each task, so you can extract and reuse PDF text without unnecessary hassle.
